Event related potential (ERP) classification
Event related potential (ERP) experiments measure the brain response to a stimulus or an event. Since the brain response to a single stimulus is usually not very visible in a single EEG trial, many trials are traditionally performed and the signals are averaged to improve the signal-to-noise ratio. Machine learning makes it possible to instead classify the response to a single stimulus. This example pipeline, EventRelatedPotentials.pyp, does that for an example data set of a flanker task, in which the participant's response was either correct or incorrect. The pipeline learns to tell the brain responses to the correct and the incorrect responses apart.
The classifier is a hierarchical discriminant component analysis (HDCA), which is a classifier that is well suited for ERPs. It is calibrated on a training recording, FlankerTrain.set, and then classifies a stream of data from a second recording, FlankerTest.set, trial by trial, as it comes in. Both are example data sets that ship with NeuroPype. The same data is used in the calibrate on prerecorded data example, which uses logistic regression instead of HDCA, and in the flanker ERP analysis example, which analyzes the ERPs of the recording.
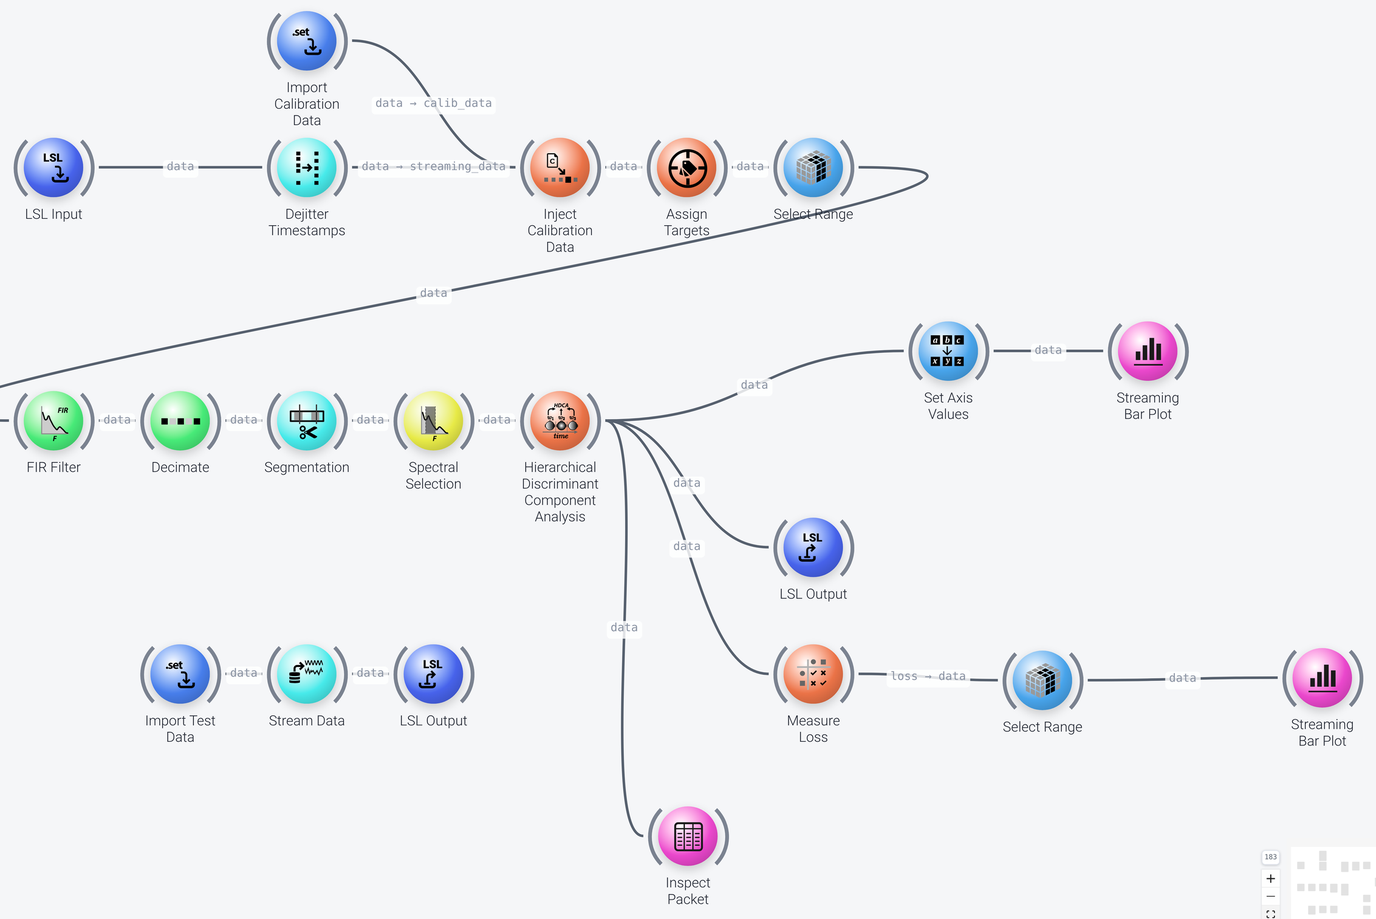
The pipeline can be divided into four parts, which we discuss in the following: data acquisition and calibration, preprocessing, classification, and the output of the results.
Data Acquisition and Calibration
Includes: Import SET, LSL Input, Dejitter Timestamps and Inject Calibration Data
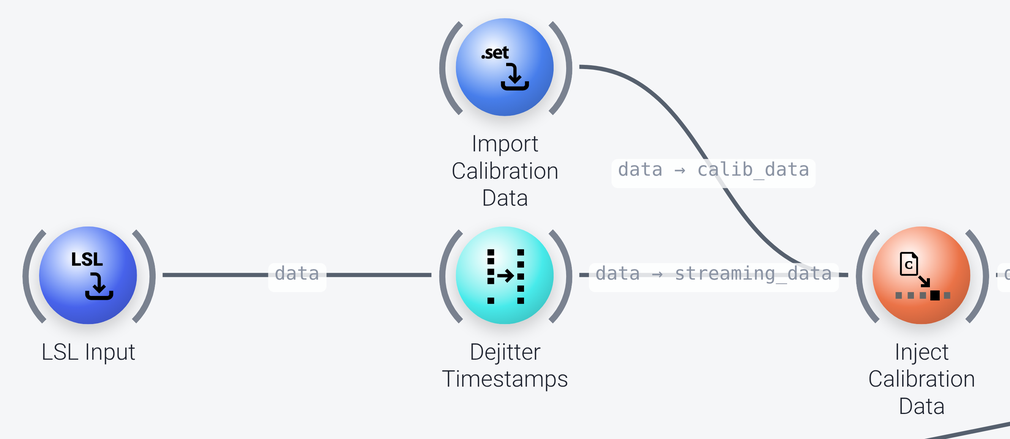
The data acquisition is the same as in the calibrate on prerecorded data example, which describes it in detail. The Inject Calibration Data node first lets the calibration recording through (from the Import SET node titled Import Calibration Data), so that the adaptive and machine learning nodes can train on it, and then lets through the streaming data, which comes from the LSL Input node and Dejitter Timestamps. Its delay_streaming_packets property is enabled, so that no streaming data is lost on the tick on which the calibration data passes.
The three nodes at the bottom of the pipeline (Import SET titled Import Test Data, Stream Data and LSL Output) play back the test recording as an LSL stream called OutStreamData (with its markers as a second stream, OutStreamData-markers), so that the example can be run without any hardware. See Data input in the example pipelines for more on this setup and for how to use your own live data. With live data, the calibration recording should come from the same device (with the same channels) as the live stream.
Preprocessing
Includes: Assign Targets, Select Range, FIR Filter, Decimate, Segmentation and Spectral Selection
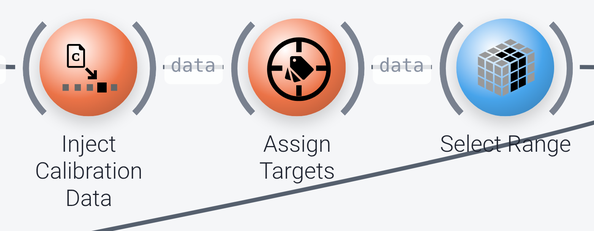
Assign Targetsassigns a target value to the markers that the classifier is trained on: itsmappingassigns 1 to the markerincorrectand 0 to the markercorrect(from theMarkercolumn, itsiv_column). The markers must exist in the data.Select Rangeremoves the last channel (selectionof:-1on thespaceaxis, usingindices), which is not an EEG channel in this data set.
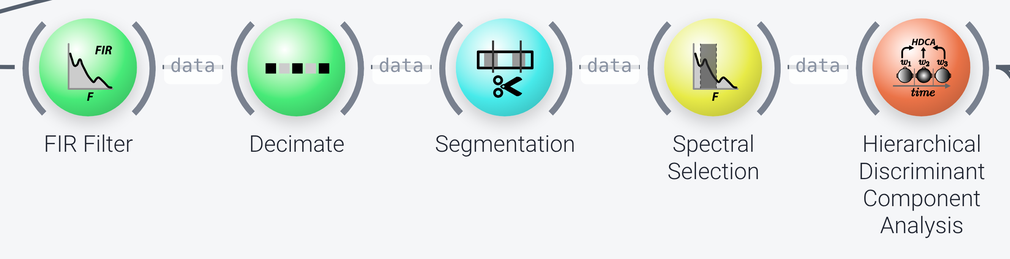
FIR Filteris a low-pass filter (frequenciesof 40 and 45 Hz), andDecimateis the node used to downsample the data after it. Itsfactoris 1 here, so that it does not change the data, but you can increase it to reduce the amount of data that the classifier processes (see the documentation of the node: it only accepts integer factors, and it needs to be preceded by a low-pass filter that removes the frequencies that cannot be represented after decimation, which is why theFIR Filteris here).Segmentationcuts the data into one segment (a trial, along theinstanceaxis) for each target marker, from 0.2 seconds before to 0.8 seconds after each marker (time_bounds). Itsonline_epochingproperty ismarker-locked, which extracts the segments around the markers in both the calibration and the streaming data. (The alternative,sliding, extracts a single segment at the end of the data on every tick, and is used when there are no markers.)Spectral Selectionfilters the segmented data to the frequencies from 0.1 to 15 Hz (frequencies), which isolates the slow cortical potentials of the ERP from higher-frequency content.
Classification
Includes: Hierarchical Discriminant Component Analysis
The Hierarchical Discriminant Component Analysis node (HDCA, last node in the previous screenshot) learns a hierarchical linear model of the time-domain signal of the trials. It can be thought of as a hierarchical version of linear discriminant analysis (LDA): first, a classifier is applied to each time slice of the segments individually, which reduces the data to a single dimension per time slice, and then a second classifier is applied to this set of one-dimensional features. It performs well on segments at full resolution, i.e., with little reduction of the channels and of the sampling rate. A shrinkage regularization is used for each of the two stages (shrinkage_within and shrinkage_across, 0.05 and 0.07). The class_weights are the prior probabilities of the two classes that the model assumes (0.5 each here). Its probabilistic property is enabled, so for each trial it outputs the probability of each class, instead of just the class label. It trains on the calibration data, and then classifies the trials of the streaming data. See the documentation of the node for more.
Output
Includes: LSL Output, Inspect Packet, Set Axis Values, Bar Plot, Measure Loss and Select Range
The results of the classification are used in several ways (see the screenshot of the whole pipeline):
- An
LSL Outputnode sends them out over LSL, as a stream calledOutStream-2(with astream_typeofControl), to be picked up by another pipeline or application in real time. - An
Inspect Packetnode shows the numerical values in a window (with the trials as rows,row_axisofinstance, and the classes as columns).
- A
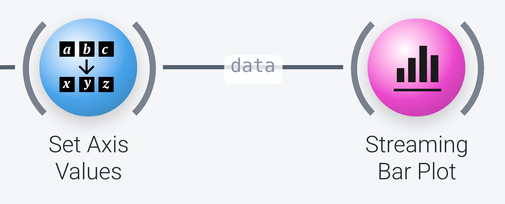
Set Axis Valuesnode names the two classescorrectandincorrect, and aBar Plotshows the predicted probability of each (with they_limitsset to 0 to 1).
- The
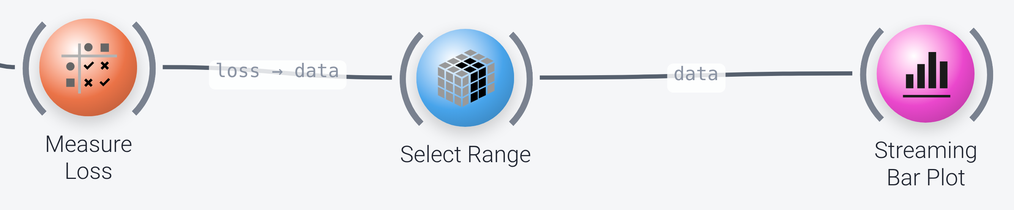
Measure Lossnode compares the predictions with the true target values of the trials (theTargetValuefield,cond_field) and computes the misclassification rate (MCR, theloss_metricsproperty), accumulated over the trials as they come in. The result is put on astatisticaxis (thestats-axisoutput_format), from which aSelect Rangenode selects thevalueitem, which is shown on a secondBar Plot.