Neural oscillatory state classification (motor imagery)
Neural oscillations indicate various neural activities or states, such as relaxation, emotions, cognitive processing and motor control. This example pipeline, MachineLearningMotorImageryClassification.pyp, shows how to harness them to classify between two states, in this case a participant imagining a movement of their left hand or of their right hand (motor imagery). The imagined movements change the power of the oscillations over the left and right motor cortex, and this is what the classifier picks up.
The main node of the pipeline is the Common Spatial Pattern (CSP) filter, in its filter bank variant, which extracts the components of the signal that best discriminate between the two classes. The pipeline is calibrated on a training recording, MotorImageryTrain.set, and then classifies a stream of data from a second recording, MotorImageryTest.set, as it comes in. Both are example data sets that ship with NeuroPype.
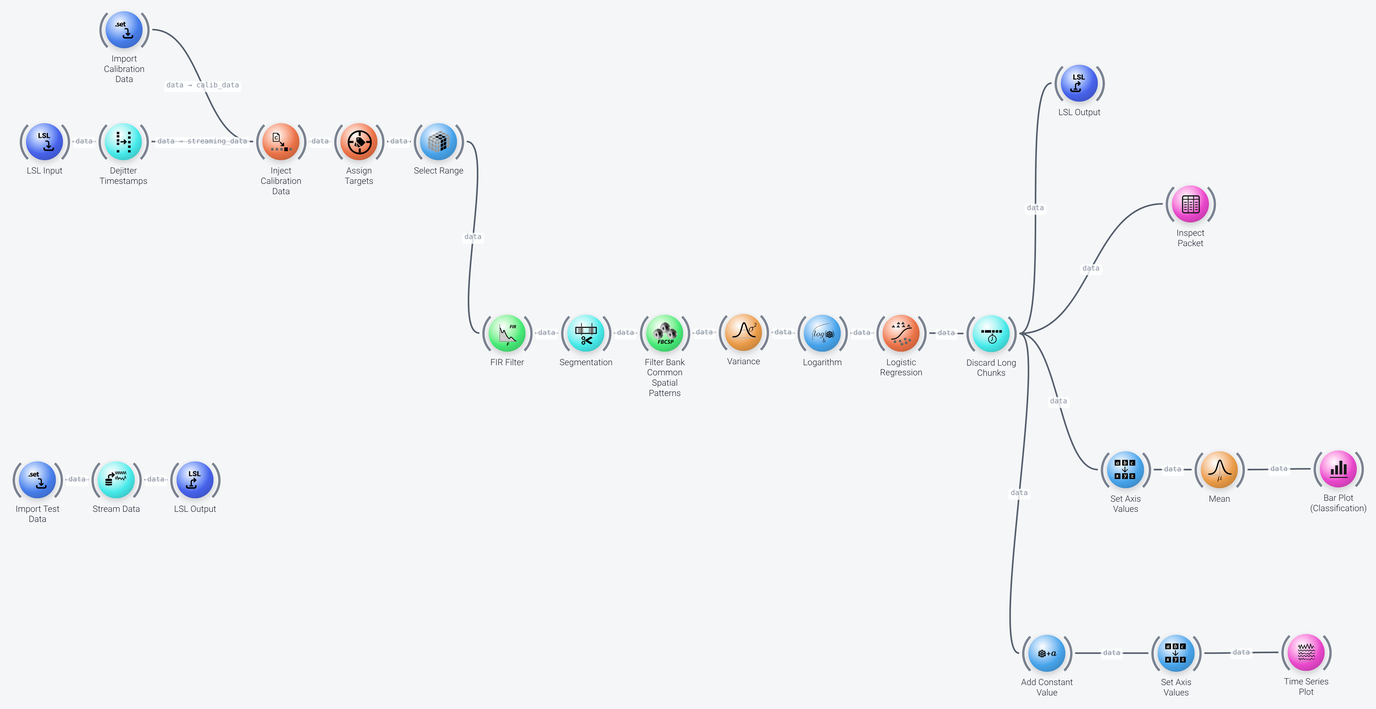
The pipeline can be divided into four parts, which we discuss in the following: data acquisition and calibration, preprocessing, classification, and the output of the results.
Data Acquisition and Calibration
Includes: Import SET, LSL Input, Dejitter Timestamps and Inject Calibration Data
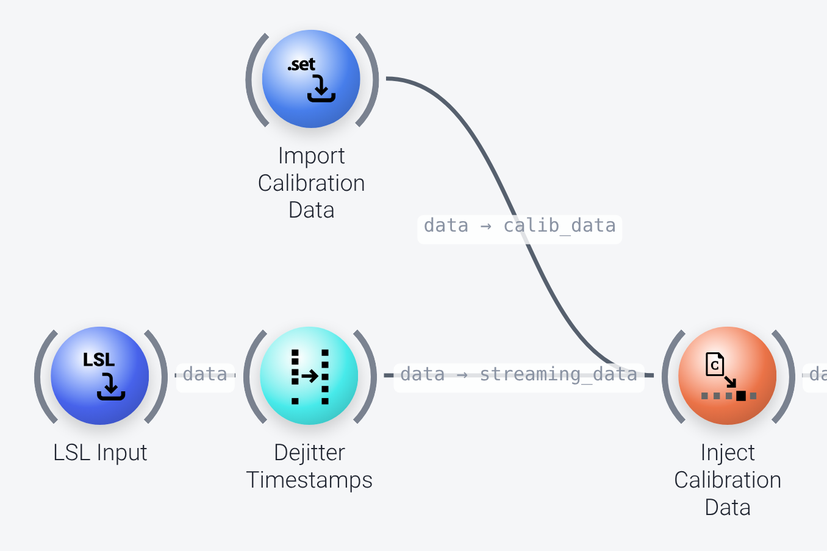
The data acquisition is the same as in the oscillatory regression and calibrate on prerecorded data examples. The Inject Calibration Data node first lets the calibration recording through (from the Import SET node titled Import Calibration Data), so that the adaptive and machine learning nodes can train on it, and then lets through the streaming data, which comes from the LSL Input node and Dejitter Timestamps. Its delay_streaming_packets property is enabled, so that no streaming data is lost on the tick on which the calibration data passes. See the calibrate on prerecorded data page for more on this node.
The three nodes in the bottom left of the pipeline (Import SET titled Import Test Data, Stream Data and LSL Output) play back the test recording as an LSL stream called OutStreamData (with its markers as a second stream, OutStreamData-markers), so that the example can be run without any hardware. See Data input in the example pipelines for more on this setup and for how to use your own live data. With live data, the calibration recording should come from the same device (with the same channels) as the live stream.
Preprocessing
Includes: Assign Targets, Select Range, FIR Filter and Segmentation
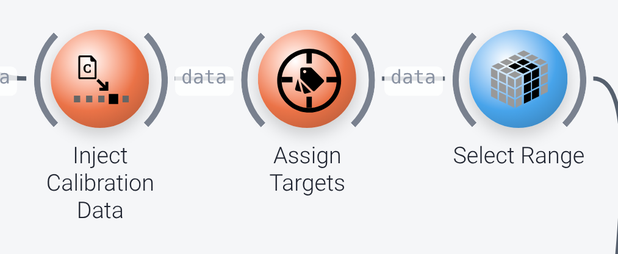
Assign Targetsassigns a target value to the markers that the classifier is trained on. Itsmappingassigns 0 to the markerleftand 1 to the markerright(from theMarkercolumn, itsiv_column), which are the markers in the data that indicate whether the participant was to imagine a movement with the left or the right hand. The markers must exist in the data.-
Select Rangeremoves the last 6 channels (selectionof:-6on thespaceaxis, usingindices), which are not EEG channels in this data set.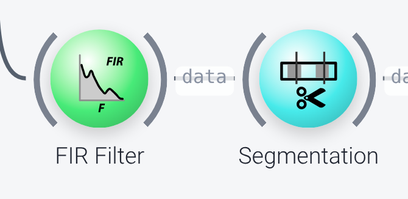
-
FIR Filteris a band-pass filter that keeps the frequencies from 4 to 42 Hz (itsfrequenciesare 2, 4, 42 and 45 Hz). Segmentationcuts the data into one segment (a trial, along theinstanceaxis) for each target marker, from 0.5 to 3 seconds after the marker (time_bounds). Itsonline_epochingproperty ismarker-locked, which extracts the segments around the markers in both the calibration and the streaming data. (The alternative,sliding, extracts a single segment at the end of the data on every tick, and is used when there are no markers.)
At this point, you could add nodes to clean the data, as in the artifact removal example.
Classification
Includes: Filter Bank Common Spatial Patterns, Variance, Logarithm, Logistic Regression and Discard Long Chunks
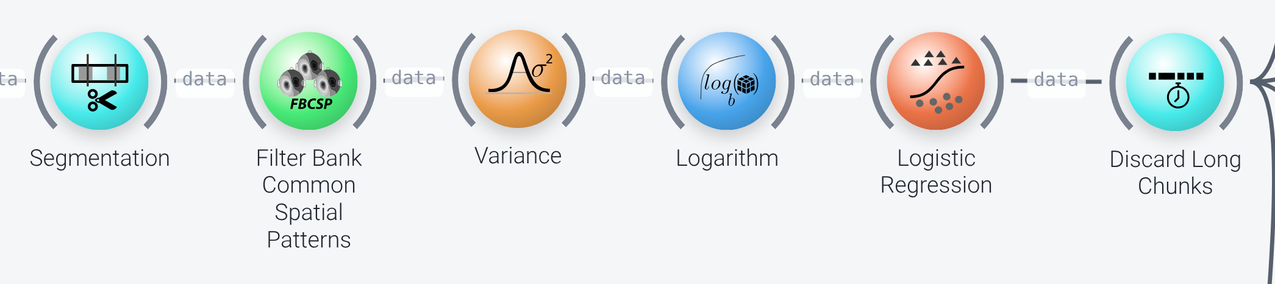
Filter Bank Common Spatial Patterns(FBCSP) extracts components whose variance optimally discriminates between the two conditions (found in theTargetValuefield,cond_field), in four frequency bands (bands: 4-7, 8-12, 13-30 and 31-42 Hz), with 3 pattern pairs per band (nof). It trains itself on the calibration data and applies the same filters to the streaming data. Other variants of this node are found in the Neural category (CSP, for instance), and can be used instead of it.Variancecomputes the variance of each component over time, which is its power in the trial, andLogarithmtakes its logarithm. These are the features for the classifier.Logistic Regressionclassifies the features. It is trained on the calibration data, with anl2regularization whose strength is chosen from the values inalphasby 5-fold cross-validation (num_folds), using accuracy as the criterion (search_metric). Itsprobabilisticproperty is enabled, so for each trial, it outputs the probability of each of the two classes, instead of just the class label.Discard Long Chunksdrops the chunks longer than 10 seconds (threshold). The calibration data goes through the pipeline first, and the long chunk that results from it should not be plotted or sent out. The results for the streaming data are short, and pass through.
Output
Includes: LSL Output, Inspect Packet, Set Axis Values, Mean, Bar Plot, Add Constant Value and Time Series Plot
The results of the classification are used in several ways (see the screenshot of the whole pipeline):
- An
LSL Outputnode sends them out over LSL, as a stream calledOutStream(with astream_typeofControl), to be picked up by another pipeline or application in real time. - An
Inspect Packetnode shows the numerical values in a window, with the markers.
- A
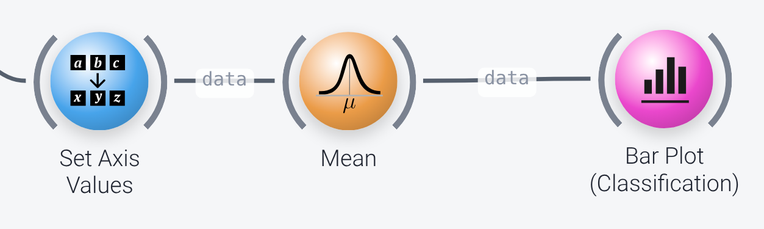
Set Axis Valuesnode names the two featuresleftandright, aMeannode averages them over the trials (theinstanceaxis), since aBar Plotrequires a 1D vector, and theBar Plotshows the average probability of each class (with they_limitsset to 0 to 1).
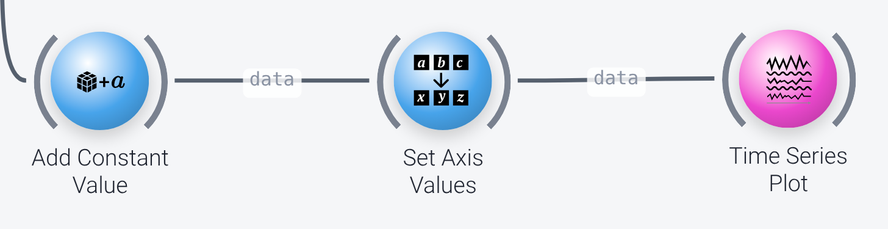
- A second branch shows the probability for each trial, over time. An
Add Constant Valuenode subtracts 0.5 (offsetof -0.5) from the probabilities, so that the zero line of each class represents a probability of 0.5, and points above the line are classified as that class. ASet Axis Valuesnode names the classes, and aTime Series Plotshows them (30 seconds,time_range) for each trial. Itsplot_markersproperty is enabled, which also plots the markers, so that the predictions can be compared with the ground truth for each trial.